Test yourself on Character Sets with exam style questions, marked instantly.
Flashcards that come back just before you would forget them.
A revision plan that remembers what you know and shows what to do next.
See which topics you have nailed and which need another look.
Quiz yourself on Character SetsGet your flashcardsBuild my revision planTrack my progressThe Universal Translator
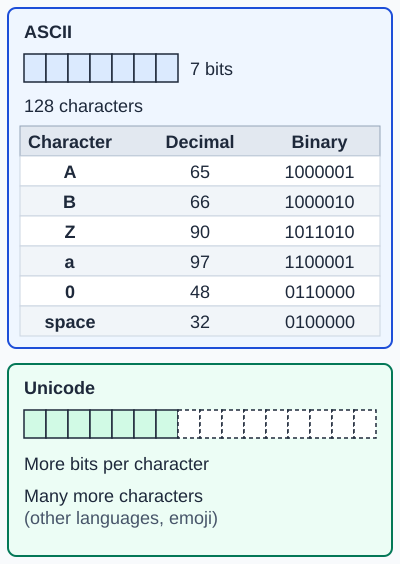
ASCII is named by all three boards. Unicode is named by AQA and OCR, not by Edexcel, which names only ASCII.
Deep Dive: Why Character Sets Matter
Computers only understand numbers (binary). To display text, we need an agreed mapping: character set = code number → symbol. Without this:
- Your 'A' might appear as '!' on my computer
- Different countries couldn't communicate digitally
- No emoji 😢
- File sharing would be impossible
Character sets are the Rosetta Stone of computing - the universal agreement that lets all computers speak the same language.
ASCII: The Foundation (1963)
ASCII = American Standard Code for Information Interchange
Key Facts:
- 7 bits: 2⁷ = 128 possible characters (0-127)
- Coverage: English alphabet, numbers, punctuation, control codes
- Designed for: English language, teletype machines, early computers
- File size: 1 byte per character (8 bits, with 1 bit spare)
ASCII Character Ranges:
  0-31:    Control characters (e.g., newline, tab, delete)
  32:      Space
  33-47:   Punctuation (! " # $ % & ' ( ) * + , - . /)
  48-57:   Digits (0-9)
  58-64:   More punctuation (: ; < = > ? @)
  65-90:   Uppercase letters (A-Z)
  91-96:   Brackets and symbols ([ \ ] ^ _ `)
  97-122:  Lowercase letters (a-z)
  123-127: More symbols ({ | } ~ DEL)
Common ASCII Codes (Memorize These!):
| Character | ASCII Code | Binary | Hex |
|---|---|---|---|
| 0 (digit) | 48 | 00110000 | 30 |
| 9 (digit) | 57 | 00111001 | 39 |
| A (uppercase) | 65 | 01000001 | 41 |
| Z (uppercase) | 90 | 01011010 | 5A |
| a (lowercase) | 97 | 01100001 | 61 |
| z (lowercase) | 122 | 01111010 | 7A |
| Space | 32 | 00100000 | 20 |
Clever ASCII Patterns:
- 'A' = 65, 'B' = 66, 'C' = 67... Sequential codes make alphabetical sorting easy
- Uppercase → Lowercase: Add 32 ('A' (65) + 32 = 'a' (97))
- Digit characters: '0'=48, '1'=49... To get numeric value, subtract 48
Extended ASCII (8-bit)
The 8-bit Expansion:
- 8 bits: 2⁸ = 256 possible characters (0-255)
- Codes 0-127: Same as standard ASCII (backward compatible)
- Codes 128-255: Extended characters (accented letters, symbols, box-drawing)
- Problem: Different "code pages" for different languages (no universal standard!)
Extended ASCII Characters (128-255):
- Accented letters: é (130), ñ (164), ü (129)
- Currency symbols: £ (156), ¥ (157), ¢ (155)
- Box-drawing: ─ │ ┌ ┐ └ ┘
- Math symbols: ± × ÷ ≈
The Extended ASCII Problem:
Code 130 might mean 'é' in Western Europe, but 'â' in Central Europe, or 'ב' in Hebrew. Files became unreadable when moved between systems. Unicode solved this chaos!
Unicode: The Universal Solution
Unicode Overview:
- Coverage: 143,859 characters (as of Unicode 15.0)
- Languages: 159 modern and historic writing systems
- Includes: Every language, emoji, math symbols, ancient scripts, musical notation
- Backward compatible: First 128 codes match ASCII
- Goal: Every character in every language gets ONE unique code
Unicode Examples:
  U+0041:  A (Latin A)
  U+03A9:  Ω (Greek Omega)
  U+4E2D:  中 (Chinese "middle")
  U+0628:  ب (Arabic letter beh)
  U+1F600: 😀 (Grinning face emoji)
  U+1F4A9: 💩 (Pile of poo emoji)
  U+00E9:  é (e with acute accent)
UTF-8, UTF-16, UTF-32: Encoding Methods
Unicode Transformation Formats (UTF):
Unicode defines WHAT each character's code is. UTF defines HOW to store those codes in bytes.
UTF-8 (Most Common):
- Variable length: 1 to 4 bytes per character
- ASCII compatible: ASCII characters still use 1 byte (efficient!)
- English text: 1 byte per character (same size as ASCII)
- Accented letters: 2 bytes (é, ñ, ü)
- Chinese/Japanese: 3 bytes per character
- Emoji: 4 bytes
- Advantages: Efficient for English, backward compatible with ASCII
- Disadvantage: Asian languages take 3× more space than UTF-16
UTF-16:
- Variable length: 2 or 4 bytes per character
- Most characters: 2 bytes (including Chinese, Japanese, Korean)
- Emoji & rare: 4 bytes (surrogate pairs)
- Use case: Windows internals, Java, JavaScript strings
- Advantage: Efficient for Asian languages
- Disadvantage: English takes 2× space vs ASCII/UTF-8
UTF-32:
- Fixed length: Exactly 4 bytes per character (always)
- Advantage: Simple - every character same size, easy indexing
- Disadvantage: Wastes space - 'A' takes 4 bytes (0x00000041)
- Use case: Internal processing where speed > space
Character Set Comparison
| Set | Size | Bytes/Char | Coverage | Use Case |
|---|---|---|---|---|
| ASCII | 128 chars | 1 byte | English only | Legacy systems, simple text |
| Extended ASCII | 256 chars | 1 byte | Western Europe | Legacy, regional documents |
| Unicode (UTF-8) | 143,859 chars | 1-4 bytes | All languages | Web, modern apps, files |
| Unicode (UTF-16) | 143,859 chars | 2-4 bytes | All languages | Windows, Java internals |
| Unicode (UTF-32) | 143,859 chars | 4 bytes | All languages | Internal processing |
Real-World Example: The Mojibake Problem
Scenario: Your friend sends you a message: "Café resumé"
- Friend's system: Saves in UTF-8 (é = 2 bytes: 0xC3 0xA9)
- Your system: Reads as ASCII (each byte = one character)
- Result: "Café resumé" (scrambled - this is called mojibake)
Why? Mismatch between encoding (UTF-8) and decoding (ASCII). The bytes 0xC3 0xA9 mean 'é' in UTF-8, but 'é' in ASCII.
Solution: Both systems must use the same character set (UTF-8 is now the web standard).
Exam Tips - Character Sets
Most common exam questions:
- "What is ASCII?" → Character set with 128 characters (7-bit), covers English alphabet, numbers, punctuation
- "Why use Unicode?" → Covers ALL languages and symbols (143,000+ characters), international support, emoji
- "ASCII code for 'A'?" → 65 (memorize this!)
- "Difference UTF-8 vs UTF-16?" → UTF-8 uses 1-4 bytes (efficient for English), UTF-16 uses 2-4 bytes (efficient for Asian languages)
- "How many bytes for ASCII character?" → 1 byte
Key facts to memorize:
- ASCII: 7-bit (128 characters), English only, 1 byte per character
- Extended ASCII: 8-bit (256 characters), accented letters
- Unicode: 143,859 characters, all languages, UTF-8/16/32 encodings
- UTF-8: 1-4 bytes, most common, web standard
- Common codes: 'A'=65, 'a'=97, '0'=48, space=32
Common mistakes to avoid:
- Confusing character set (Unicode) with encoding (UTF-8) - they're related but different!
- Saying ASCII is 8-bit - NO! Standard ASCII is 7-bit (128 characters)
- Thinking Unicode uses more space - depends on encoding! UTF-8 is same as ASCII for English
- Mixing up 'A' (65) and 'a' (97) - uppercase ≠ lowercase
Quick Reference - Character Sets
ASCII Quick Codes:
- Space = 32
- Digits: '0'=48 to '9'=57
- Uppercase: 'A'=65 to 'Z'=90
- Lowercase: 'a'=97 to 'z'=122
- Lowercase = Uppercase + 32
Character Set Evolution:
- 1960s: ASCII invented (128 characters, English)
- 1980s: Extended ASCII (256 characters, regional)
- 1991: Unicode created (universal standard)
- Today: UTF-8 dominates (95% of web pages)
Why Unicode Won:
- One standard for ALL languages (no more code pages!)
- Backward compatible with ASCII
- Emoji support 😀
- UTF-8 is efficient for English while supporting everything
Make this stick
Signing in gives access to all PrepWise features.